Post-incident review form for AI latency
When an LLM API latency incident happens, a spike in time-to-first-byte (TTFB) across regions, a provider degradation, or a routing failure, the natural instinct is to fix it and move on. But a structured post-incident review transforms that outage into institutional knowledge. For platform teams relying on OpenRouter, OpenAI, or other external AI endpoints, a post-incident review form becomes the difference between learning and repeating the same failure.
Photo by Pavel Danilyuk from Pexels
When an LLM API latency incident happens, a spike in time-to-first-byte (TTFB) across regions, a provider degradation, or a routing failure, the natural instinct is to fix it and move on. But a structured post-incident review transforms that outage into institutional knowledge. For platform teams relying on OpenRouter, OpenAI, or other external AI endpoints, a post-incident review form becomes the difference between learning and repeating the same failure.
This resource walks you through building and running a post-incident review process tailored to AI API latency incidents. We'll cover the anatomy of a solid review form, how to capture the right metrics, and how to convert findings into preventive measures that stick.
TL;DR
- A post-incident review form captures timeline, root cause, and follow-up actions in one structured artifact, reducing blame and enabling learning.
- Document baseline latency before an incident (TTFB, TTFT, regional variance) so you can measure deviation accurately during post-mortems.
- Link every finding to a concrete action: alert threshold tuning, regional failover setup, or provider contract review.
- Conduct reviews within 48 hours of incident resolution while details are fresh; assign one owner to drive completion.
- Share a summary with stakeholders (product, finance, ops) so non-technical leaders understand latency as a product risk, not just a technical metric.
Why post-incident reviews matter for latency
Latency incidents in AI APIs are often invisible until users complain. A chat feature that adds 2–3 seconds of delay doesn't trigger a traditional uptime alert, the service is still "online." But latency degrades the user experience and can indirectly cause churn.
Latency incidents are also harder to root-cause than binary outages because they have degrees of severity. A TTFB spike from 300 ms to 800 ms in one region might be triggered by provider load, network jitter, or a misconfigured regional fallback. Without a structured post-incident process, teams often settle on a surface-level explanation ("OpenRouter was slow that day") and miss systemic problems (missing geo-redundancy, missing baseline monitoring, or poor alert thresholds).
"The way you approach a post-incident review is just as important as the tasks that need to be ticked off.">, Post
A post-incident review form ensures that every latency incident generates three artifacts: a timeline, a root cause analysis, and a list of preventive actions. Over time, these reviews reveal patterns, e.g., "our European TTFB drops every Tuesday morning", that justify investment in better monitoring or regional failover.
Anatomy of a solid post-incident review form
A post-incident review form should collect three layers of information: context, analysis, and action.
Layer 1: Incident context
Start with the basics: what happened, when, and who noticed it.
- Incident ID: A unique identifier (e.g.,
INC-2024-0847). This makes it easy to reference later and link to Slack threads, status page posts, or tickets. - Title: A one-line summary. Examples: "OpenRouter TTFB spike in US-East, 15 min", "OpenAI chat completion timeouts across all regions, 45 min".
- Discovery method: Was it caught by a Observinio alert, a user complaint, a support ticket, or manual observation? This tells you whether your monitoring is working.
- Start time (UTC) and end time (UTC): Precise timestamps. If resolution was gradual, record when you first saw improvement.
- Severity: Choose a category (e.g., "low" = <5 min, <1 % traffic affected; "high" = >30 min, >10 % traffic affected). This helps prioritize follow-up effort.
- Affected components: List the providers, regions, and endpoints involved. Example: "OpenRouter Claude 3 Sonnet, US-East, US-West; OpenAI GPT-4, all regions".
Layer 2: Metrics and baseline
Before you analyze root cause, anchor your findings in data.
- Baseline TTFB (by region): What was the normal TTFB before the incident? If you don't have this, add a note to establish baselines for future incidents. Observinio's daily probes store historical baselines across 21 regions, so you can compare incident behavior to normal traffic.
- Peak TTFB during incident: Record the maximum observed TTFB per region. Example: "US-East: 2400 ms (baseline 320 ms), EU-West: 1800 ms (baseline 280 ms)".
- TTFT (time-to-first-token): If applicable, record this too. TTFB and TTFT often behave differently; a spike in TTFB without TTFT change suggests a queuing problem, not a model performance issue.
- Traffic volume: Did incident occur during peak load? Off-peak? Knowing the traffic context helps you distinguish between "the provider was overloaded" and "our config broke".
- Error rate: If applicable, log the percentage of requests that timed out or returned errors.
Layer 3: Root cause analysis
This is where learning happens. Use the structured "five whys" or a fishbone diagram, but keep it practical for latency.
- Primary cause: The single most likely trigger. Examples: "OpenRouter ingestion service hit CPU ceiling", "DNS failover for EU endpoint took 90 seconds", "Our regional router was misconfigured for load balancing".
- Contributing factors: Secondary issues that made the incident worse or harder to detect. Example: "We had no TTFB alert set below 1 second, so latency degraded for 8 minutes before anyone noticed".
- Detection delay: How long passed from incident start to detection? If it was >10 minutes, why? This often points to missing alerts.
- Resolution time: How long from detection to fix? Note any manual steps that could be automated.
Building your post-incident review process
Step 1: Schedule the review within 48 hours
Hold the review meeting while context is fresh and people still have Slack threads open. Don't wait a week. Assign one owner (usually the on-call engineer or an SRE) to drive the meeting and ensure the form gets completed.
Step 2: Gather participants
Include:- The on-call engineer or whoever detected/resolved the incident.
- An SRE or platform engineer (for systemic context).
- A representative from product or customer success if the incident was customer-facing.
- Optionally, an observer from another team (for knowledge sharing).
Step 3: Walk through the timeline
Use Observinio alerts, logs, and Slack threads to build a minute-by-minute timeline. Write it down:
- 13:42 UTC: Observinio alert fires: "TTFB >1s in US-East". [Why wasn't this caught earlier? Did the alert threshold miss a gradual creep?]
- 13:47 UTC: On-call engineer checks OpenRouter status page; no reported issues.
- 13:49 UTC: On-call checks Observinio dashboard for regional comparison; confirms spike is US-East only.
- 13:52 UTC: On-call triggers failover to secondary US-East endpoint.
- 13:55 UTC: TTFB returns to baseline (320 ms).
Step 4: Document root cause and contributing factors
Use the fishbone framework to separate primary cause from context:
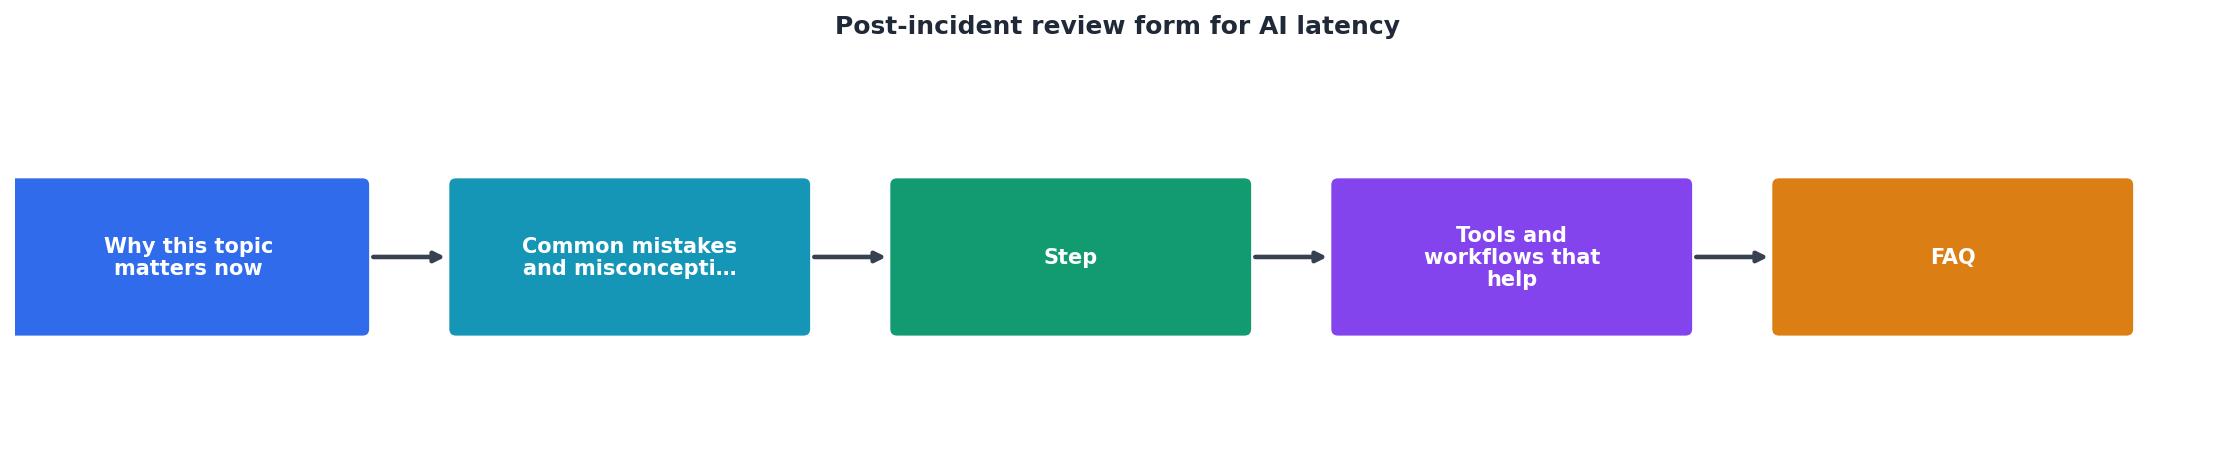
Root cause: OpenRouter's ingestion service hit CPU ceiling due to a surge in traffic from a large customer's batch job.
Contributing factors:- No customer traffic limits were in place; provider doesn't throttle gracefully.
- Alert threshold was set to >1 second, but degradation started at ~600 ms and lasted 3 minutes before breaching.
- Secondary endpoint failover wasn't automated; required manual intervention.
Step 5: Generate action items with owners and deadlines
Every finding must lead to an action. Vague actions ("improve monitoring") don't stick. Concrete actions do:
| Finding | Action | Owner | Deadline | Success Metric |
|---|---|---|---|---|
| No alert for TTFB >600 ms | Lower alert threshold to 500 ms TTFB in Observinio | SRE team | 1 week | Alert fires before user impact |
| Manual failover took 3 min | Implement automated failover to secondary endpoint | Platform eng | 2 weeks | <30 sec failover time, tested monthly |
| No traffic limits | Review OpenRouter contract re: rate limits, implement local queueing | CTO + Ops | 1 month | SLA added to contract, queueing live |
| Slow detection (5 min) | Set up Observinio email alert + Slack notification for TTFB spikes | SRE | 3 days | On-call gets notified in <1 min |
Step 6: Share findings with stakeholders
Write a one-page summary (the form itself, or a digest) and share with:- Leadership: "This incident cost us X hours of slower chat experience. Here's what we're fixing and why it matters to our customers."
- Product: "Our latency SLO is now <500 ms TTFB. Here's how it compares to competitors." (Use this to justify investment in regional presence or provider diversity.)
- Finance: "We're adding a secondary provider for failover; cost is $Y per month, ROI is preventing Z incidents/quarter."
Post-incident review form template
Your progress is saved automatically in your browser.
Post-Incident Review Checklist
A structured post-incident review minimizes mean time to learning (MTTL) by establishing baseline metrics before incidents occur, documenting precise timelines during the review meeting, and converting each finding into a measurable action item with clear ownership. This approach transforms reactive firefighting into proactive reliability engineering.
FAQ
Frequently Asked Questions
Keep latency visible and actionable
A post-incident review form is only useful if it leads to action. Use Observinio's daily probe data and degradation alerts to establish rock-solid baselines, so your reviews are anchored in real numbers, not guesses. When your team reviews latency incidents with precision, you move from "the provider was slow" to "we need better regional failover," and that's where real reliability is built.
For consistent latency tracking across your LLM API usage, set up Observinio monitoring across OpenRouter, OpenAI, and other endpoints in all 21 regions. That data becomes your evidence base for every post-incident review. Start free at observinio.com.
Additional Resources
- Post-incident review best practices | Jira Service ... - 1. Decide which incidents need review · 2. Draft your review within two days of the incident · 3. Assign roles and owners · 4. Work from a template · 5. Include a ...
- Post incident review AI agent - This AI agent generates a post-incident review report for the user to review and revise after a major incident report.
- Post-Incident Review (PIR): How-To's & Best-Practices Guide - A Post-Incident Review (PIR) is a structured process, typically resulting in a written report, that examines why an IT. AI-assisted incident ...
Monitor AI API latency from 22 regions
Observinio runs daily probes against OpenRouter and OpenAI endpoints and emails you when latency degrades.
Set up alerts