Mistral probe configuration worksheet
Mistral's API powers chat completions, function calling, and embeddings across production teams worldwide. Yet latency visibility into Mistral endpoints is often an afterthought, tracked only when users start complaining or requests time out. This worksheet helps you configure synthetic probes to monitor Mistral latency continuously, detect regional degradation before it affects your users, and make data-driven decisions about routing and provider fallbacks.

Mistral's API powers chat completions, function calling, and embeddings across production teams worldwide. Yet latency visibility into Mistral endpoints is often an afterthought, tracked only when users start complaining or requests time out. This worksheet helps you configure synthetic probes to monitor Mistral latency continuously, detect regional degradation before it affects your users, and make data-driven decisions about routing and provider fallbacks.
TL;DR
- Set up daily probes from 21 global regions to measure Mistral TTFB (time to first byte) and request latency.
- Baseline typical response times for your target models so you can detect degradation early.
- Configure alerts when latency spikes above your SLO threshold, with email notifications and a live status page.
- Use weekly summaries to spot patterns (time-of-day peaks, regional variance) and optimize routing.
- Mistral's documentation confirms the unified agent approach; real-world latency varies by region and model.
Why Mistral latency monitoring matters
Mistral has become a backbone for teams building agentic workflows and real-time chat experiences. Unlike batch inference, these production use cases demand predictable low-latency response times. A 2-second TTFB might pass a test; a 5-second TTFB will break user experience and spike support tickets.
Regional variance adds another layer of complexity. A request from your European users may hit a different Mistral cluster than your Asia-Pacific traffic. Without synthetic probes, you miss the signal until support escalation happens. Observinio's 21 global regions let you test Mistral latency from your actual user locations, measure TTFB and TTFT (time to first token) separately, and spot regional bottlenecks before they cascade.
Key Takeaway: Synthetic probes from 21 global regions enable early detection of Mistral latency degradation before it affects users, allowing your team to make data-driven failover decisions and optimize request routing for production reliability."The unified agent for productivity and coding.">, Documentation
What you'll measure
Before diving into probe setup, understand the key metrics:
- TTFB (Time to First Byte), the delay from sending a request to receiving the first byte of the response. For streaming models, this includes Mistral's initial processing time.
- Total latency, the end-to-end time to get the complete response. For long-context or complex function-calling tasks, this can vary widely.
- Regional variance, the difference in latency between regions. A 200 ms TTFB from US-East may become 600 ms from Singapore if routing is suboptimal.
- Error rate, requests that fail or timeout, often correlated with regional overload or provider incidents.
Setting up your probe configuration
Step 1: Collect your baseline parameters
Before configuring probes, gather these details:
- Mistral API endpoint (e.g.,
https://api.mistral.ai/v1/chat/completions) - API key (stored securely; never commit to version control)
- Target model(s) (e.g.,
mistral-7b,mistral-medium,mistral-small) - Request payload, a realistic prompt and settings matching your production traffic
- Expected SLO threshold, your latency ceiling in milliseconds (e.g., 500 ms TTFB)
- Alert recipients, email addresses for Observinio notifications
Step 2: Design a representative test payload
Use a payload that reflects real traffic. Avoid trivial single-token requests; they do not stress the API in the same way production queries do. Here is a template:
{
  "model": "mistral-7b",
  "messages": [
    {
      "role": "user",
      "content": "Analyze the following customer support ticket and suggest a response category (bug, feature request, or general inquiry): 'I cannot export my data to CSV. It times out after 30 seconds.'"
    }
  ],
  "temperature": 0.7,
  "max_tokens": 256
}
This payload is neither trivial nor excessive, it mirrors typical chat completion work. When you configure probes, Observinio will send this exact payload from each of the 21 regions every 24 hours by default (configurable to more frequent intervals).
Step 3: Define your SLO and alert thresholds
Establish clear latency targets:
- P50 (median) TTFB target: The latency that 50% of requests should meet. For Mistral from most regions, 300–400 ms is reasonable.
- P95 TTFB target: The latency that 95% of requests should stay under. Aim for 700–1000 ms.
- Alert trigger: Set Observinio to page or email you if any region's TTFB exceeds your P95 threshold for three consecutive probes.
Step 4: Enable multi-region probes
Observinio supports probes from 21 global regions: US East, US West, EU-Central, EU-West, Singapore, Tokyo, Sydney, Mumbai, São Paulo, and others. You do not need to enable all; focus on regions where your users concentrate.
For example, a US-first SaaS might start with US-East and US-West, then add EU-Central if European usage grows. An international platform would activate at least one probe per major region.
Each probe runs independently and reports latency directly to Observinio's dashboard. Regional latency is stored separately, so you can compare and spot which regions are degrading.
Step 5: Configure the probe schedule
Daily probes (once per 24 hours per region) are sufficient for most teams. This strikes a balance: enough data to detect trends, infrequent enough to avoid rate-limit issues or cost overruns if you are paying per API call.
If you suspect time-of-day variance (e.g., Mistral latency spikes during US peak hours), upgrade to twice-daily probes from your primary regions. The Observinio dashboard will show temporal patterns in the weekly summary.
Step 6: Set up alerts and escalation
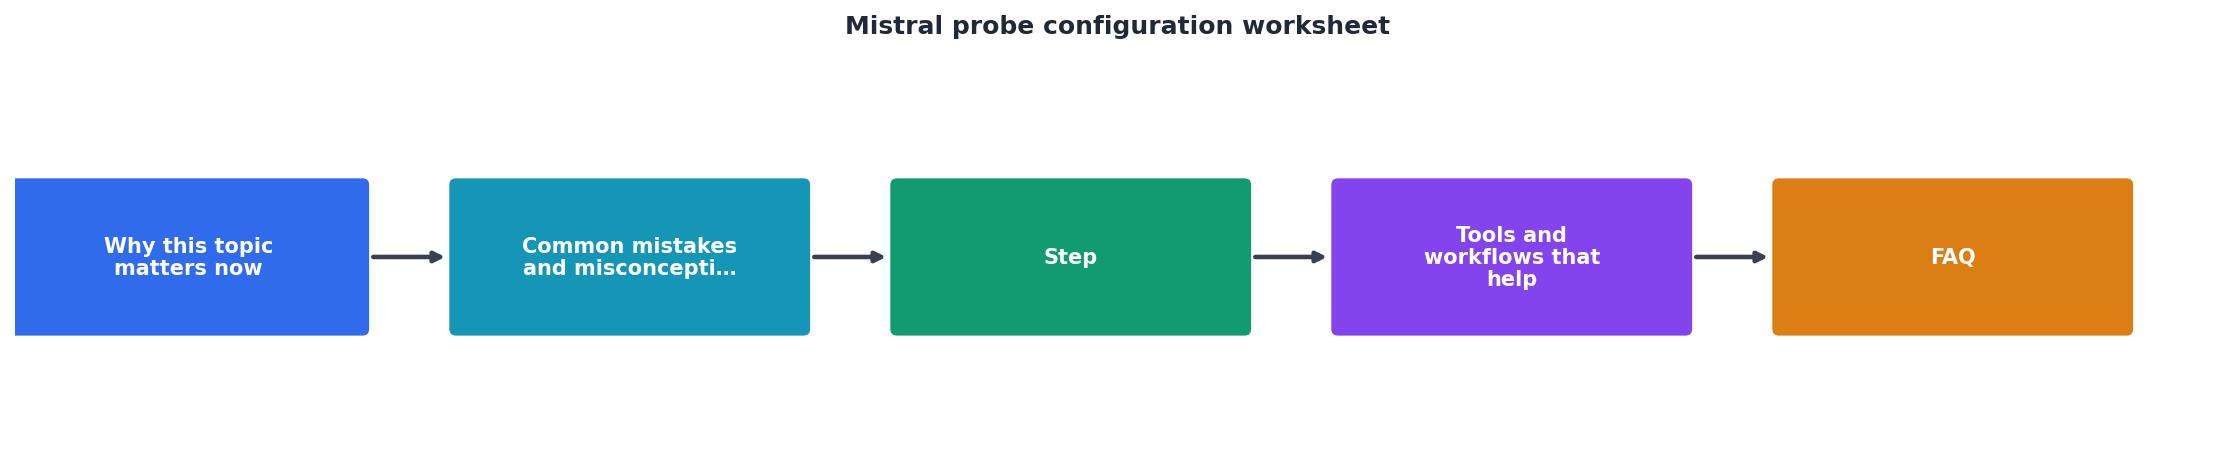
Configure alerts in Observinio:
- Email notifications when a region's latency exceeds your SLO threshold for 3 consecutive probes.
- Slack webhook (if available) to post alerts to your #incidents channel.
- Weekly digest summarizing regional latency trends, error rates, and anomalies.
IfWhen an alert fires, your on-call engineer can:us-east-1TTFB > 800 ms for 3 consecutive probes, send email toplatform-team@company.comand notify#mistral-incidentsSlack channel.
- Check Mistral's status page for known incidents.
- Compare latency with OpenRouter or direct provider latency (if you monitor both) to isolate the problem.
- Decide whether to fail over to a fallback model or region.
Practical probe configuration checklist
Use this checklist to ensure your Mistral probes are production-ready:
Your progress is saved automatically in your browser.
Investigating latency anomalies
When an alert fires, follow this playbook:
- Check the Observinio dashboard. View the latency spike: is it global or regional?
- Compare regions. If only Singapore is slow but US-East is normal, the issue is likely Mistral's regional infrastructure, not a global outage.
- Check Mistral status page. Visit
status.mistral.ai(or check their public status) to see if they have posted a maintenance window or incident. - Review model performance. If you test multiple models (e.g.,
mistral-7bandmistral-medium), compare their latencies. High variance suggests model-specific load. - Check your own stack. If only one region is slow but Observinio probes are latency-isolated, the bottleneck may be your request router or retry logic, not Mistral.
- Escalate or fail over. If Mistral latency exceeds your SLO for more than 30 minutes, consider switching traffic to a fallback provider (OpenRouter, OpenAI) or degrading to a faster model until Mistral recovers.
Regional latency patterns and optimization
Once you have one week of baseline data, analyze it for patterns:
- Time-of-day peaks: Does latency spike during US or EU business hours? This suggests provider-side load scaling.
- Regional variance: Is Singapore consistently 300 ms slower than US-East? This is normal but may justify a regional routing policy.
- Model variance: Do larger models (e.g.,
mistral-medium) have higher baseline latency than smaller ones? Yes, always. Factor this into your SLO targets.
- Route traffic to faster regions when available. If your app runs in multiple regions, prefer routing requests to the Mistral endpoint closest to your user's geography.
- Pre-warm connections. Keep long-lived HTTP/2 connections open to Mistral's endpoint; cold starts add 100–200 ms.
- Batch requests when possible. If your use case allows it, batch multiple user requests into one larger API call to amortize Mistral's overhead.
- Upgrade the SLA. If you are paying for Mistral API access, ask about regional redundancy or priority queuing. Mistral's commercial tier may offer lower-latency endpoints or guaranteed uptime.
Monitoring beyond latency
Latency is only one dimension of API health. Expand your probes to also track:
- Error rate: What % of probes fail or time out? A spike in 5xx errors often precedes latency degradation.
- Token count variance: Do responses have consistent token counts, or is variance high? Variance can indicate model inconsistency or queuing delays.
- Cost per request: Track the USD cost per probe (if you are paying per token). Correlated with latency spikes, cost increases may signal Mistral's load-based pricing kicking in.
FAQ
Frequently Asked Questions
mistral-small vs. mistral-medium), or route requests to OpenRouter or OpenAI? Third, if the issue is regional, consider using a multi-region failover strategy where requests from Singapore route to the closest Mistral endpoint.Next steps
Start by creating a test probe for Mistral's chat completion endpoint. Run it daily for one week from 3–5 regions, collect baseline latency data, and calculate your P50 and P95 thresholds. Once you have a week of clean data, configure email alerts set 10–15% above your P95, then integrate Observinio's weekly summary into your platform team's review meeting.
If you use multiple LLM providers, set up identical probes for each one. Observinio's dashboard will let you compare latency across providers and regions, giving you the data to optimize your routing and failover strategy.
For help setting up Mistral probes or configuring region-specific alerts, visit Observinio's status page or contact the team.
Additional Resources
- Documentation - Mistral AI - Learn how to deploy and use Mistral AI's Large Language Models with our comprehensive documentation, guides, and tutorials.
- Mistral Integration with Orkes Conductor - This guide explains how to integrate Mistral with Orkes Conductor. Here's an overview: Get the required credentials from Mistral. Configure a new Mistral ...
- Product Datasheet Analysis using Document AI - Learn Product Datasheet Analysis using Document AI with practical examples and code snippets using Mistral AI's LLMs.
Monitor AI API latency from 22 regions
Observinio runs daily probes against OpenRouter and OpenAI endpoints and emails you when latency degrades.
Set up alerts