Latency data export for executive reports
When your LLM API experiences degradation in Tokyo but your dashboard only shows a global average, you're flying blind. Executives asking "why are chatbot responses slow?" need more than a shrug, they need data. The problem is that raw latency metrics from 21 regions, collected across multiple providers and time zones, are nearly impossible to digest in a boardroom. This guide shows how to export and present latency data in a format that drives real decisions: faster regional routing, provider changes, and infrastructure investment.
Photo by Wolfgang Weiser from Pexels
When your LLM API experiences degradation in Tokyo but your dashboard only shows a global average, you're flying blind. Executives asking "why are chatbot responses slow?" need more than a shrug, they need data. The problem is that raw latency metrics from 21 regions, collected across multiple providers and time zones, are nearly impossible to digest in a boardroom. This guide shows how to export and present latency data in a format that drives real decisions: faster regional routing, provider changes, and infrastructure investment.
TL;DR
- Export latency data from Observinio daily probes across all 21 regions to identify regional bottlenecks and provider variance that dashboards hide.
- Structure exports for executives: trend lines, outlier weeks, cost-per-millisecond trade-offs, and regional heatmaps that tell a story.
- Automate weekly summary generation and email delivery to remove manual reporting friction.
- Use latency baseline comparisons to justify provider switches or multi-region routing changes with measurable evidence.
- Schedule exports around business cycles: daily for ops, weekly for leadership, monthly for board-level capacity planning.
Why latency data matters for business decisions
A 200-millisecond delay in TTFB (time to first byte) sounds technical. To a product manager, it translates to customer churn. To finance, it is the difference between a profitable expansion into APAC and a failed market entry. Yet most organizations lack a clean way to report on latency trends, and leadership cannot fund what they cannot measure.
"In a 2024 survey by Gartner, over 60 percent of data leaders ranked "reducing time to action" as their top priority for analytics investments.">, Decision Latency Reduction in Business Intelligence
The cost of latency blindness is real. When you do not know whether OpenRouter is slower than OpenAI direct in Singapore, you cannot make an informed routing decision. When you do not track weekly TTFT (time to first token) trends, you miss the chance to catch a degradation before it affects SLOs. And when you cannot show executives a six-month trend with regional variance highlighted, budget for monitoring infrastructure does not get approved.
Exporting latency data from continuous probes solves this. It decouples monitoring from visibility. Instead of asking teams to log in and read dashboards, data comes to them, in email, in Slack, in a report ready for the Monday morning standup.
Key latency metrics for executive-level reports
Not all latency metrics are created equal. Executives care about three things: business impact, trend, and actionability. Here are the core metrics your export should surface:
Time to First Byte (TTFB)
TTFB is the latency from request to the server's first response bit. For chat applications, this directly affects perceived responsiveness. A TTFB spike from 150 ms to 400 ms in a single region is a red flag. Your export should show:
- Weekly TTFB median and p95 per region
- Week-over-week percentage change
- Flagged regions where TTFB exceeded SLO
Time to First Token (TTFT)
TTFT matters for streaming responses. It is the delay before the first token arrives, a proxy for backend queueing or model-serving latency. Unlike TTFB, TTFT includes model inference, so it reflects API provider health and capacity.
- Track TTFT separately from TTFB to diagnose whether delays come from networking or the provider
- Compare TTFT across providers for the same region to justify provider selection
End-to-End Latency (E2E)
E2E captures total request-to-last-token time. For executive reports, show:
- Median E2E by region and provider
- Growth or shrinkage week-to-week
- Percentile distribution (p50, p95, p99) to expose tail latency that SLAs miss
Regional variance and outliers
Latency is not uniform. A provider may perform well in North America but degrade in Europe or APAC. Your export must highlight:
- Heatmap: which region-provider combination is slowest
- Standard deviation or interquartile range to show consistency
- Week-over-week outlier flags: if a region jumped 300 ms, it matters
Cost-per-millisecond
Finance loves this metric. Calculate API cost divided by latency (e.g., cost per 100 ms of response time). This justifies premium providers or multi-region routing:
- Provider A: $0.0008 per 100 ms E2E response
- Provider B: $0.0012 per 100 ms E2E response
- Conclusion: Provider A delivers better value
How to structure and export latency data
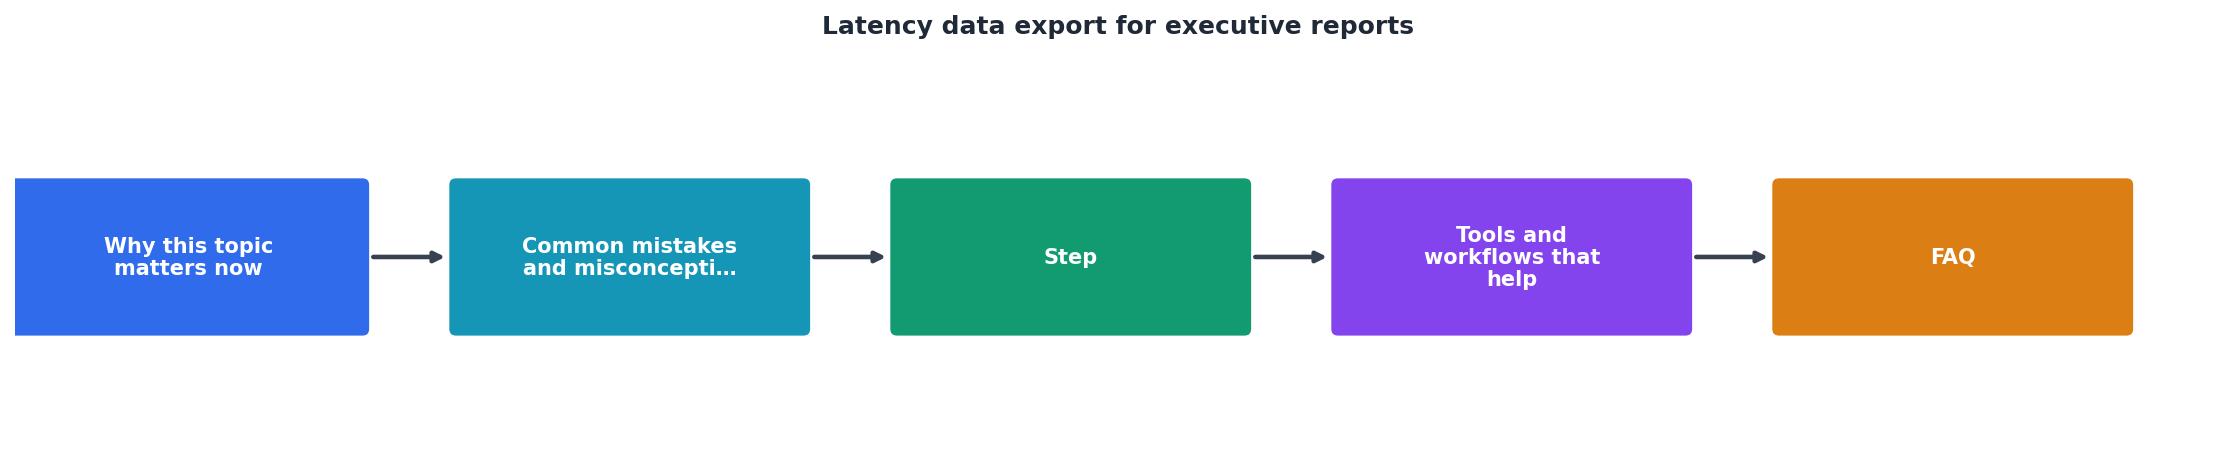
💡 Pro tip:
Automate your export pipeline to run off-peak (2 AM UTC) and eliminate manual reporting friction. This frees your team to focus on analysis and action rather than data collection.
Step 1: Define your export schedule and audience
Before you build, decide who gets what and when:
- Ops team (daily): Raw data export, all 21 regions, TTFB/TTFT/E2E, last 24 hours. Use CSV for further analysis.
- Engineering leads (weekly): Curated summary, top 5 slowest regions, week-over-week trend, any region above SLO threshold.
- Executives (weekly/monthly): Narrative export, 2–3 key findings with trend charts, regional heatmap, and cost justification.
Step 2: Query and extract latency data
Use Observinio's data export API (or direct database access if self-hosted) to pull:
Query latency data for all regions
Filter: last 7 days
Metrics: TTFB, TTFT, E2E (median, p95, p99)
Providers: OpenRouter, OpenAI direct, [others]
Export format: JSON or CSV
Automated scripts (Python, Node, or scheduled workflows) should run daily at 2 AM UTC, pulling the prior 24 hours of data and appending to a rolling weekly file.
Step 3: Transform and enrich the data
Raw numbers are noise. Transform them for clarity:
- Calculate week-over-week deltas (e.g., "TTFB up 12% vs last week")
- Flag outliers: any region > 2 standard deviations from weekly baseline
- Group by region, then by provider, so comparison is easy
- Add context: "North America TTFB is 150 ms (baseline: 145 ms, +3.4%)"
Step 4: Generate the report
A strong export includes:
- Executive summary (3 lines): Top finding, any SLO breach, one recommendation.
- Regional breakdown table: Region | TTFB | TTFT | E2E | Status (Green/Yellow/Red)
- Provider comparison chart: Visual showing OpenRouter vs OpenAI latency per region.
- Trend line (7-day or 30-day): Line graph of median TTFB week-over-week.
- Heatmap: Region × Provider grid showing latency intensity (color-coded).
Step 5: Distribute and automate
- Use email templates (HTML or PDF) for weekly executive summaries.
- Post daily CSVs to a shared S3 bucket or internal wiki for ops.
- Set up Slack alerts if any region latency > SLO threshold.
- Schedule the export pipeline in your CI/CD or data warehouse (e.g., Airflow, dbt, or native database jobs).
Building the executive narrative
Numbers without context are noise. Shape your export to answer the question your audience is asking:
- "Should we switch providers?" → Cost-per-millisecond table, six-week trend comparing both.
- "Why are users slow in Europe?" → Regional TTFB heatmap highlighting EU regions, sorted by degradation severity.
- "Can we scale traffic?" → p99 latency growth curve, if p99 is stable or declining, headroom exists.
Practical export checklist
Your progress is saved automatically in your browser.
FAQ
Frequently Asked Questions
[region][provider][metric][timestamp]. In your export, create side-by-side columns for each provider within a region. This makes provider comparison immediate: "OpenRouter TTFB in Singapore: 210 ms; OpenAI direct: 185 ms." Finance and product can then weigh cost against performance.Next steps: turn data into action
Latency data is worthless if it sits in a spreadsheet. The goal is to move from "We have data" to "We made a decision based on data." Start with a single weekly export email to your engineering leads. Include one chart and one recommendation. Watch the conversation shift from "I think latency is fine" to "Let's switch regions based on this week's numbers."
Observinio's 21-region daily probes give you the raw material. Your export pipeline gives you the story. Together, they build the evidence base that turns latency from an abstract concern into boardroom-ready insight.
Ready to export your first report? Begin with Observinio's status page to see real latency data from your providers, then set up an automated export pipeline using the checklist above. Your executives, and your users, will notice the difference.
Additional Resources
- Time delay in exporting reports - Online help - One of the main reasons for delay in report exports is the large volume of report entries. To reduce the report export time, we recommend you generate and ...
- Decision Latency Reduction in Business Intelligence - This article explores proven approaches to reducing decision latency in BI, outlining tools, frameworks, and workflows … ing, formatting, and distributing ...
- Reporting Latency: The Problem with Outdated Business ... - Sales exports its data. This is reporting latency. The solution is not putting every metric on a real-time dashboard. Different decisions ...
Monitor AI API latency from 22 regions
Observinio runs daily probes against OpenRouter and OpenAI endpoints and emails you when latency degrades.
Set up alerts