Photo by Enzo Cetrangolo from Pexels
Production LLM APIs are expensive to benchmark. Running thousands of real requests against OpenAI or OpenRouter to measure latency impacts your bill and skews their metrics. Shadow traffic, a technique borrowed from high-reliability infrastructure, solves this by duplicating a portion of live requests to a test environment without affecting the main response path. For AI API teams, shadow traffic unlocks honest, real-world latency measurements across regions, providers, and configurations without paying for double traffic or waiting weeks for synthetic data to become representative.
TL;DR
- Shadow traffic copies a small percentage (1–5%) of production API calls to a separate endpoint for measurement without impacting user-facing responses.
- Use shadow traffic to compare OpenAI, OpenRouter, and other providers side-by-side under identical load conditions.
- Regional latency variance emerges only under real traffic patterns; synthetic probes from a single region miss critical slowdowns.
- Implement shadow traffic incrementally: start with status-code logging, then add latency buckets, then deep payload diffs.
- Observinio's 21-region probe network complements shadow traffic by catching degradation patterns synthetic-only monitoring misses.
Why Shadow Traffic Matters for LLM Benchmarks
Most teams measure LLM API latency one of two ways: synthetic probes (test requests from fixed regions) or production logs (what you see after the fact). Both have blind spots.
Synthetic probes give you uptime metrics but miss geographic variance. If you probe OpenAI from a single region every 60 seconds, you won't spot that US East is 200 ms slower than US West under real traffic. Probes also cost money, running 1,000 requests per day against a paid API adds up fast.
Production logs capture real latency but arrive too late for remediation. By the time you query yesterday's logs to investigate a slowdown, users have already complained. Logs also don't isolate provider issues from your own routing layer or middleware.
Shadow traffic bridges this gap. By mirroring 1–5% of live traffic to a test endpoint, you measure latency under realistic load patterns without doubling your API bill or surfacing test responses to users. You see how each provider actually behaves when your users hit it, not how it behaves when pinged once a minute.
For platform teams at companies like Replit or Vercel that route millions of requests daily, shadow traffic is non-negotiable: you need to know whether a provider degradation is real before your on-call engineer wakes up.
How Shadow Traffic Works
Conceptually, shadow traffic is simple: intercept outbound API calls, duplicate a fraction to a shadow endpoint, and log both responses. In practice, the routing and comparison logic requires care.
The Basic Flow
- Intercept: Your LLM client library or middleware observes each outbound API call.
- Decide: Based on a deterministic hash of the request (user ID, timestamp, etc.), decide whether to shadow this request. For 2% shadowing, hash the request and sample if hash % 100 < 2.
- Duplicate: Fire the same request (or a variation) to a shadow endpoint or alternate provider without waiting for the response.
- Compare: Log status code, TTFB (time to first byte), TTFT (time to first token), and total latency from both the main and shadow paths.
- Report: Aggregate metrics daily and expose them in dashboards or email alerts.
Architecture Pattern
User Request
    ↓
[Middleware / Client]
    ├→ Main Provider (OpenAI) → Response to User
    └→ [Sampler] → Shadow Provider (OpenRouter) → Log, don't return
The key: the shadow call is fire-and-forget from the user's perspective. Even if the shadow endpoint times out, the main response is unaffected.
Setting Up Shadow Traffic for Your Stack
Implementing shadow traffic requires a few architectural decisions. Here's a step-by-step approach:
Your progress is saved automatically in your browser.
Step 1: Choose Your Shadow Target
- Same provider, different region: Route 2% of US East traffic to US West OpenAI. Reveals regional latency variance without provider risk.
- Different provider: Route 2% of OpenAI traffic to OpenRouter. Measures provider delta under real load.
- Test configuration: Route 2% to a staging instance of your own LLM router. Validates new routing logic before rollout.
Step 2: Implement Deterministic Sampling
Use a consistent hash to decide which requests shadow. This ensures the same user's requests are sampled consistently (reproducible for debugging) and distributes load evenly.
import hashlib

def should_shadow(user_id: str, shadow_rate: float = 0.02) -> bool:
    """Deterministically sample requests for shadowing."""
    hash_val = int(hashlib.md5(user_id.encode()).hexdigest(), 16)
    return (hash_val % 100) < (shadow_rate  100)
Step 3: Fire-and-Forget the Shadow Request
Spawn the shadow request in a background thread or async task so latency is decoupled from the main path:
import threading
import time

def call_llm_with_shadow(provider_url: str, shadow_url: str, payload: dict, user_id: str):
    """Call main provider; shadow a percentage of requests."""

    # Main call
    start = time.time()
    response = requests.post(provider_url, json=payload, timeout=30)
    main_latency = time.time() - start

    # Shadow call (background)
    if should_shadow(user_id):
        def shadow_call():
            shadow_start = time.time()
            try:
                shadow_resp = requests.post(shadow_url, json=payload, timeout=30)
                shadow_latency = time.time() - shadow_start
                log_shadow_metric(user_id, main_latency, shadow_latency,
                                  response.status_code, shadow_resp.status_code)
            except Exception as e:
                log_shadow_error(user_id, str(e))

        threading.Thread(target=shadow_call, daemon=True).start()

    return response
Step 4: Log Structured Metrics
Capture enough detail to be useful later:
{
  "timestamp": "2025-09-02T14:23:45Z",
  "user_id": "user_123",
  "request_id": "req_abc",
  "main_provider": "openai",
  "shadow_provider": "openrouter",
  "main_ttfb_ms": 145,
  "shadow_ttfb_ms": 167,
  "main_ttft_ms": 320,
  "shadow_ttft_ms": 355,
  "main_status": 200,
  "shadow_status": 200,
  "main_tokens": 450,
  "shadow_tokens": 450
}
Step 5: Aggregate and Alert
Daily, compute percentiles and trends:
import pandas as pd

df = pd.read_json('shadow_metrics.jsonl', lines=True)

print("Main TTFB (ms):")
print(df['main_ttfb_ms'].describe())

print("\nShadow TTFB (ms):")
print(df['shadow_ttfb_ms'].describe())

divergence = (df['main_status'] != df['shadow_status']).sum()
print(f"\nStatus divergence: {divergence} / {len(df)} ({100divergence/len(df):.2f}%)")
If shadow latency consistently exceeds main by >50 ms, or divergence exceeds 1%, trigger an alert.
Comparing Providers at Scale
One of shadow traffic's most effective uses is provider comparison under identical real-world load. Instead of ping-ponging between Datasheet claims and vendor benchmarks, you see OpenAI vs. OpenRouter latency for the exact models and concurrency your users generate.
The Comparison Setup
Route a week of shadow traffic to each provider for the same region and model. Collect TTFB, TTFT, and error rates:
| Provider | P50 TTFB (ms) | P95 TTFB (ms) | P50 TTFT (ms) | Error Rate |
|---|---|---|---|---|
| OpenAI US-East | 78 | 185 | 280 | 0.2% |
| OpenRouter US-East | 92 | 210 | 310 | 0.5% |
Handling Response Diff
Shadow responses will differ from main responses (different models, different inference runs). Focus on metadata:
"Bound the diff cost: sample 1–5% of responses for deep diff; for the rest, compare status codes and payload size buckets.">, Medium
For 100% of shadow requests: compare HTTP status and token count. For a random 2% subset: do token-by-token diff to catch semantic changes or routing bugs.
Combining Shadow Traffic with Synthetic Probes
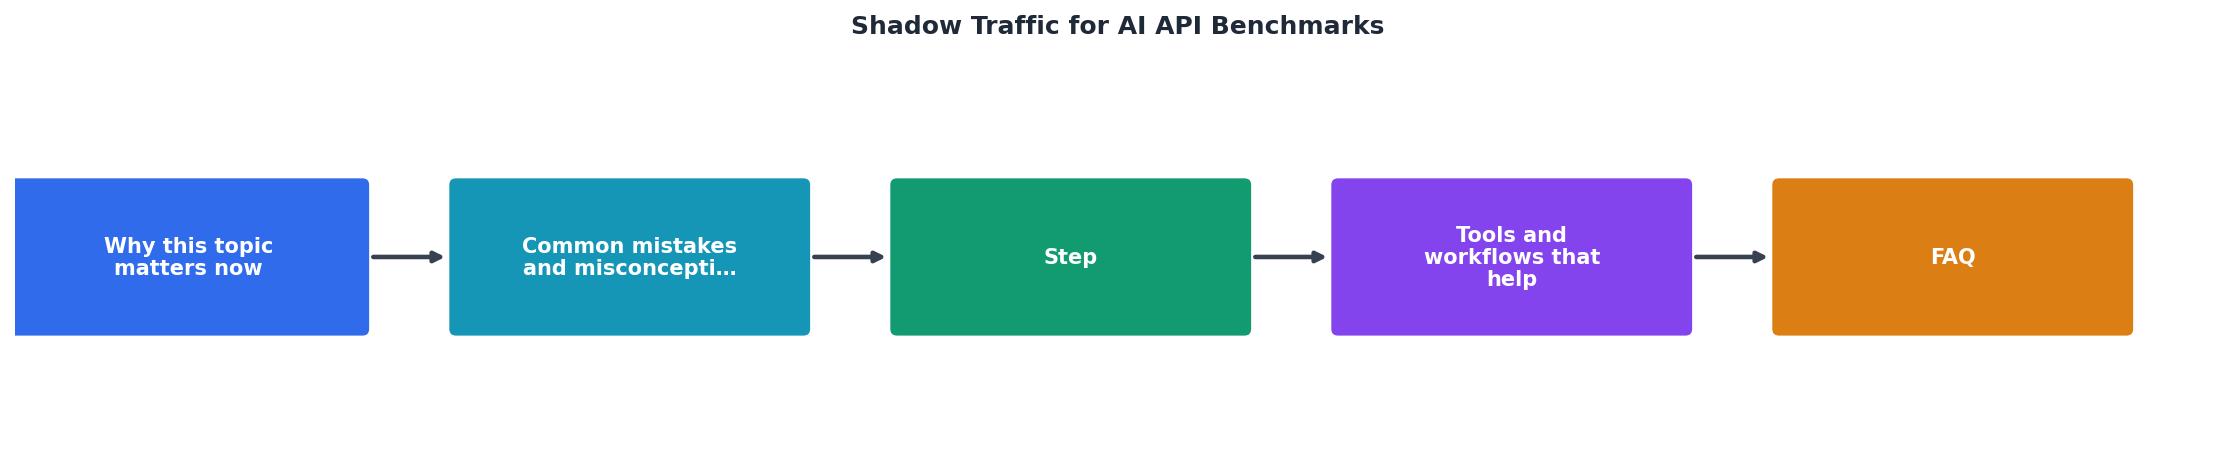
Shadow traffic and synthetic probes serve different purposes and work best together.
Synthetic probes (like Observinio's 21-region network) detect absolute degradation: "OpenAI US-East is 500 ms slower than baseline today." Probes run on a fixed schedule, so you can compare day-over-day and spot regressions early.
Shadow traffic detects relative degradation under load: "When real users hit us at peak concurrency, OpenRouter latency spikes 30% vs. our baseline." Shadow traffic only happens during user traffic, so it's invisible during off-hours, but it's the signal that matters for SLOs.
Recommendation: Use Observinio daily probes to detect provider-wide outages and regional slowdowns. Use shadow traffic to validate provider switches and catch load-dependent issues your probes miss.
Common Pitfalls and Solutions
Pitfall 1: Sampling bias. If you only shadow requests from a subset of users, you miss cold-start artifacts or user-specific provider routing. Solution: Use deterministic hashing keyed to request properties, not user type.
Pitfall 2: Shadow latency skews main latency. If shadow calls contend with main calls for the same connection pool, you've introduced a confound. Solution: Use a separate HTTP client and connection pool for shadow requests.
Pitfall 3: Silent failures. Shadow call timeouts or errors go unnoticed. Solution: Log every shadow call; trigger an alert if shadow error rate exceeds 2%.
Pitfall 4: Stale data. You log shadow metrics but never query them. Solution: Schedule a weekly summary report and expose dashboard links in Slack or email.
FAQ
Frequently Asked Questions
Next Steps
Shadow traffic is an investment that pays off when you operate at scale or depend on multiple providers. Start small: implement deterministic sampling this week, log shadow latency next week, and set up a daily summary by end of month.
Pair shadow traffic with Observinio's daily probes from 21 regions to get both deep (load-dependent) and broad (global baseline) latency data. Set up email alerts when shadow latency diverges more than 10% from baseline or status codes start to diverge. That combination, shadow traffic plus multi-region synthetic monitoring, gives you the signal you need to move fast and route confidently.
Additional Resources
- Top 7 Shadow Traffic Techniques to Prove Performance - Seven practical shadow traffic techniques — mirroring, sampling, write suppression, replay, and diffing — to prove performance without risking ...
- How to Roll Out New LLMs Safely Using Shadow Testing - Shadow traffic helps assess output quality differences before any user exposure. You'll catch regressions in tone, accuracy, or formatting that ...
- The 2026 State of AI Traffic & Cyberthreat Benchmark Report - AI-driven traffic nearly tripled in 2025. AI agent traffic grew 7851%. eight times faster than human traffic 187% AI-driven traffic growth. Traffic from AI ...