Photo by Darya Sannikova from Pexels
Regional latency spikes are among the hardest incidents to diagnose. Your API works perfectly in North America, but users in Europe report timeouts. Your dashboards show aggregate metrics that look fine. Support tickets pile up before you realize the problem is isolated to one geographic region, and by then, you've lost time and trust.
This article walks you through detecting, diagnosing, and responding to regional degradation on OpenRouter (or any multi-region LLM API). You'll learn how to distinguish between provider issues, routing problems, and your own infrastructure, and how to use regional latency data to make faster decisions during incidents.
TL;DR
- Regional spikes on OpenRouter often go unnoticed because aggregate dashboards hide them; you need per-region probes to catch them early.
- Use OpenRouter's geographic routing to identify whether the problem is the provider, your exit point, or the user's network.
- Set up degradation alerts for each region independently; a spike in one region should not trigger a full on-call rotation.
- Observinio's 21-region probes and daily baselines let you compare OpenRouter's real-world latency against your SLO and detect regional variance before users do.
- Document regional thresholds in your runbooks so on-call engineers can decide whether to failover, route around the region, or wait for recovery.
Why Regional Spikes Feel Invisible
Most observability stacks collapse latency metrics into a single number: average response time, p95, or p99 across all requests. When OpenRouter experiences a regional outage, say, EU-based endpoints serving requests 3–4× slower than baseline, the aggregate metric might barely budge if 80% of your traffic routes through US regions.
"The initial impact was partial: roughly 20% of requests failed with 500 errors.">, OpenRouter Outages on February 17 and 19, 2026, OpenRouter Blog
A partial outage hitting one region can feel like a mystery. Your application logs show errors. Your provider status page says "all systems operational." Your monitoring team sees no red flags in the headline metrics. Meanwhile, a subset of your users are hitting timeouts, and you're flying blind.
The fix is straightforward in principle: monitor each region independently. In practice, this requires:
- Probes deployed or triggered from multiple geographic points.
- Per-region SLOs and alert thresholds, not a single global threshold.
- A clear incident classification: is this regional, global, or local?
- A routing or failover plan that can act on regional signals.
Setting Up Regional Latency Baselines
Before you can detect a spike, you need to know what "normal" looks like for each region. This baseline becomes your reference point during incidents.
Build Daily Baselines from Synthetic Probes
The most reliable way to collect regional latency data is to send synthetic probes from multiple regions on a regular schedule. Observinio probes 21 regions including US East, US West, EU Central, EU West, Asia Pacific, and several others. Each probe sends a small request to your OpenRouter endpoint (e.g., a 50-token completion) and measures TTFB (time to first byte) and total request latency.
By running probes every hour (or every 15 minutes for higher sensitivity), you build a distribution of latencies per region. After a week or two, patterns emerge:
- Asia-Pacific regions might show higher baseline latency (250–400 ms TTFB) due to distance.
- US East typically has the lowest latency (80–120 ms TTFB).
- EU regions cluster around 150–250 ms, depending on which city and which OpenRouter edge server answers.
Define Per-Region Thresholds
A global SLO like "TTFB under 500 ms" is too coarse. Instead, define thresholds per region based on your baselines:
| Region | Baseline TTFB (p95) | Alert Threshold | Rationale |
|---|---|---|---|
| US East | 120 ms | 300 ms | 2.5× baseline = significant degradation |
| US West | 140 ms | 350 ms | 2.5× baseline |
| EU Central | 180 ms | 450 ms | 2.5× baseline |
| EU West | 200 ms | 500 ms | 2.5× baseline |
| Asia Pacific | 300 ms | 750 ms | 2.5× baseline |
Detecting the Spike: Monitoring and Alerts
Detection speed matters. The faster you identify a regional spike, the faster you can route traffic away or notify users. Observinio's daily probes and degradation alerts are built for this.
Alert on Degradation, Not Absolute Latency
Rather than alerting when latency crosses a fixed threshold, alert when it deviates from the baseline. This catches spikes even if the absolute latency is still acceptable.
For example:- Alert fires if EU Central TTFB exceeds baseline p95 by more than 50% for 5 consecutive minutes.
- Alert does not fire if a single probe is slow; you need a pattern.
Set Up Weekly Summary Reports
Observinio sends weekly summaries showing latency trends, regional comparison, and anomalies. These reports help you spot subtle patterns that alerts might miss: a region that is slowly degrading over three days, or an hour of each day where one region is consistently slower.
Configure Email or Slack Alerts for Incident-Level Events
Connect your monitoring system to Slack or email so that on-call engineers get immediate notification when a regional alert fires. Include:
- Which region is affected.
- Current latency vs. baseline.
- Duration of the spike (if multi-minute).
- A direct link to the Observinio dashboard for that region.
Diagnosing the Root Cause
An alert fires: "EU West TTFB up 200% for 10 minutes." Now what? The cause could be:
- OpenRouter infrastructure issue in the EU region.
- Your own routing or exit point sending traffic inefficiently.
- Network congestion between you and OpenRouter.
- Upstream issues (e.g., the LLM provider that OpenRouter routes to).
Check the OpenRouter Status Page
First, visit openrouter.io/status or subscribe to their incident notifications. If they have reported an EU incident, the root cause is likely on their side, and your next action is communication and waiting.
Compare Your Probe Data Against Public Benchmarks
If OpenRouter has not reported an incident, check Observinio's provider dashboard for OpenRouter. If the spike is visible in multiple regions' probes to OpenRouter, it is a global OpenRouter issue. If it is isolated to one region, it is regional.
Send a Test Request from Your Application and from a Different Region
Have your application log which OpenRouter region/endpoint it used for the failed request. Send the same model request from a different geographic region (e.g., spin up a test container in US East if the problem is EU West). If the test succeeds quickly from US East but fails from EU West, the issue is regional routing or infrastructure.
Check Your Own Network Path
If the spike is isolated to one of your outbound regions (e.g., you send OpenRouter requests through a VPN exit in Frankfurt, and that exit is congested), the problem is your routing, not OpenRouter. Coordinate with your infrastructure team to check:
- Packet loss on the route from your exit to OpenRouter's endpoint.
- BGP changes or route flaps.
- Load on the exit point itself.
Triangulate with Error Rates and Error Types
If latency spikes and error rates jump, check what errors are being returned:
- 429 (rate limit): OpenRouter is throttling; likely their infrastructure is overloaded.
- 500 / 502 / 503 (server errors): OpenRouter backend is failing; definitely their infrastructure.
- Timeout / connection reset: Network issue or OpenRouter edge proxy is slow to respond.
- No errors, just slow: OpenRouter is handling the request but the LLM inference is slow (e.g., model queue is long).
Incident Response Playbook
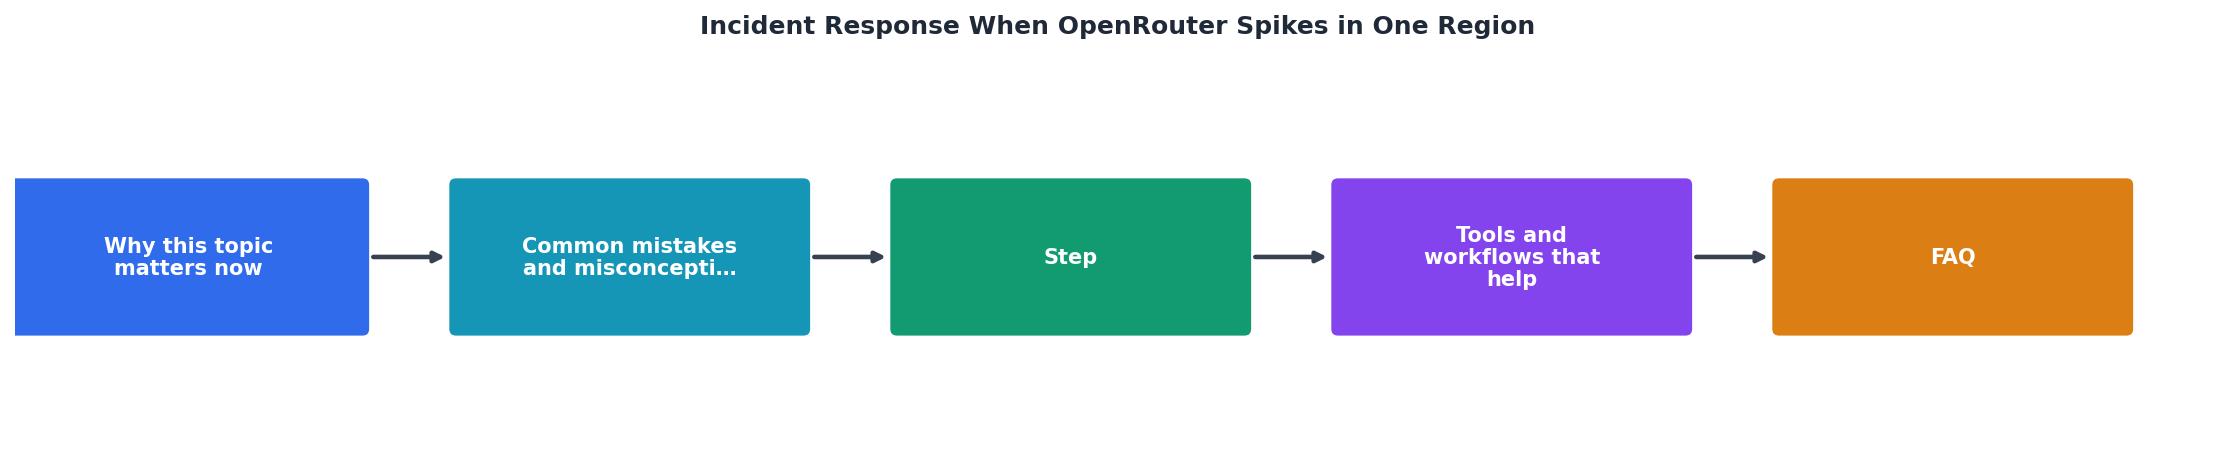
Use this step-by-step checklist when a regional alert fires.
Your progress is saved automatically in your browser.
Step 1: Verify the Alert (1–2 minutes)
- Open the Observinio dashboard for the affected region.
- Confirm that latency is elevated and the spike is sustained (not a one-off probe glitch).
- Check Observinio's probe history: did the spike start at the same moment across multiple probes?
Step 2: Check the Provider Status (1 minute)
- Visit OpenRouter's status page.
- Check their Twitter / status feed for any reported incidents.
- If an incident is listed, note the affected region and estimated duration.
Step 3: Diagnose the Scope (2–3 minutes)
- Run a test request from your application to OpenRouter, flagging the region/endpoint used.
- If available, run the same request from an unaffected region.
- Check error rates in your application logs for the affected region.
Step 4: Decide: Wait or Failover (2 minutes)
- If the spike is under 5 minutes old: Wait and re-check. Many spikes resolve within 5 minutes.
- If the spike is 5+ minutes old and OpenRouter has not acknowledged: Escalate to your on-call platform engineer and consider failover.
- If error rates are climbing: Failover immediately; every minute of delay increases customer impact.
Step 5: Update Stakeholders (1 minute)
- Post to your war room (Slack, PagerDuty, or incident tool).
- Notify affected customers if degradation is visible to them (e.g., slower chat responses).
- Set an expectation: "We are routing around OpenRouter's EU region. Service degradation is expected to last 10 minutes."
Step 6: Post-Incident Review (After recovery)
- Document what you learned: was it OpenRouter's issue, your routing, or something else?
- Update your runbook with any new steps or thresholds.
- If you failed over, measure the impact: how many requests were affected before failover?
Building a Robust Regional Routing Strategy
Once you have detected a regional spike, your ability to respond depends on how flexible your routing is.
Load-Balance Across Regions, Not Just Models
Instead of picking a single OpenRouter endpoint and using it globally, load-balance across multiple regional endpoints. Observinio lets you monitor each endpoint independently, so you can make routing decisions in real time.
Example Python pseudocode:
def route_completion_request(user_prompt, user_region):
    """Route to least-latent OpenRouter region."""

    available_regions = ["us-east", "us-west", "eu-central", "eu-west", "asia-pacific"]

    # Get current latency for each region from Observinio (or cached local data)
    latencies = observinio_client.get_latest_latencies(
        provider="openrouter",
        regions=available_regions
    )

    # Filter out degraded regions (if latency > threshold)
    healthy_regions = [r for r in available_regions if latencies[r] < LATENCY_THRESHOLD]

    if not healthy_regions:
        # All regions are degraded; use least-bad
        healthy_regions = available_regions

    # Route to lowest-latency healthy region
    best_region = min(healthy_regions, key=lambda r: latencies[r])

    openrouter_url = f"https://openrouter.io/api/v1/completions?region={best_region}"
    response = requests.post(openrouter_url, json={"prompt": user_prompt, ...})

    return response
This approach requires that you either:
- Know which OpenRouter region each endpoint is closest to (contact OpenRouter support).
- Have control over which endpoint you call (some OpenRouter plans allow region pinning).
- Use a DNS or load-balancer layer that can route based on region health.
Cache and Timeout Aggressively
During a regional spike, use short timeouts (2–5 seconds instead of 30 seconds) and cache results aggressively. If a user's request times out, serve a cached response or fallback message rather than burning CPU and user patience waiting for a slow API.
Have a Degraded-Mode Plan
Define what "degraded" means for your product:
- Can you serve chat requests from cached embeddings?
- Can you show a loading message instead of a real-time response?
- Can you queue the request and send the result via email or webhook?
FAQ
Frequently Asked Questions
Getting Ahead of Regional Spikes
The best incident response is one you never have to execute. Observinio's daily probes and 21-region baseline data help you stay ahead:
- Daily summaries show regional variance before it becomes a crisis.
- Degradation alerts fire on deviation, not absolute values, catching subtle shifts early.
- Audit trails let you correlate spikes with provider changes, routing updates, or traffic surges.
Your support team will notice the difference first: fewer complaints about "slow requests in Europe." Your on-call team will notice it second: fewer 3 a.m. pages for phantom issues. Your users will notice it last—they will just enjoy fast, reliable chat experiences. That is the goal of regional monitoring and incident response discipline.
Additional Resources
- OpenRouter Outages on February 17 and 19, 2026 - OpenRouter experienced related outages caused by failures in a third-party caching dependency. A portion of users saw 500 or 401 errors on all ...
- State of AI 2025: 100T Token LLM Usage Study - This approach ensures comparability across model families and minimizes bias from transient spikes or regional time-zone effects.
- An Empirical 100 Trillion Token Study with OpenRouter - This approach ensures comparability across model families and minimizes bias from transient spikes or regional time-zone effects. 3 Open vs.